Tool · Python + SQLite
Media Index
Thirty terabytes of drives turned into one SQLite database you can ask questions of.
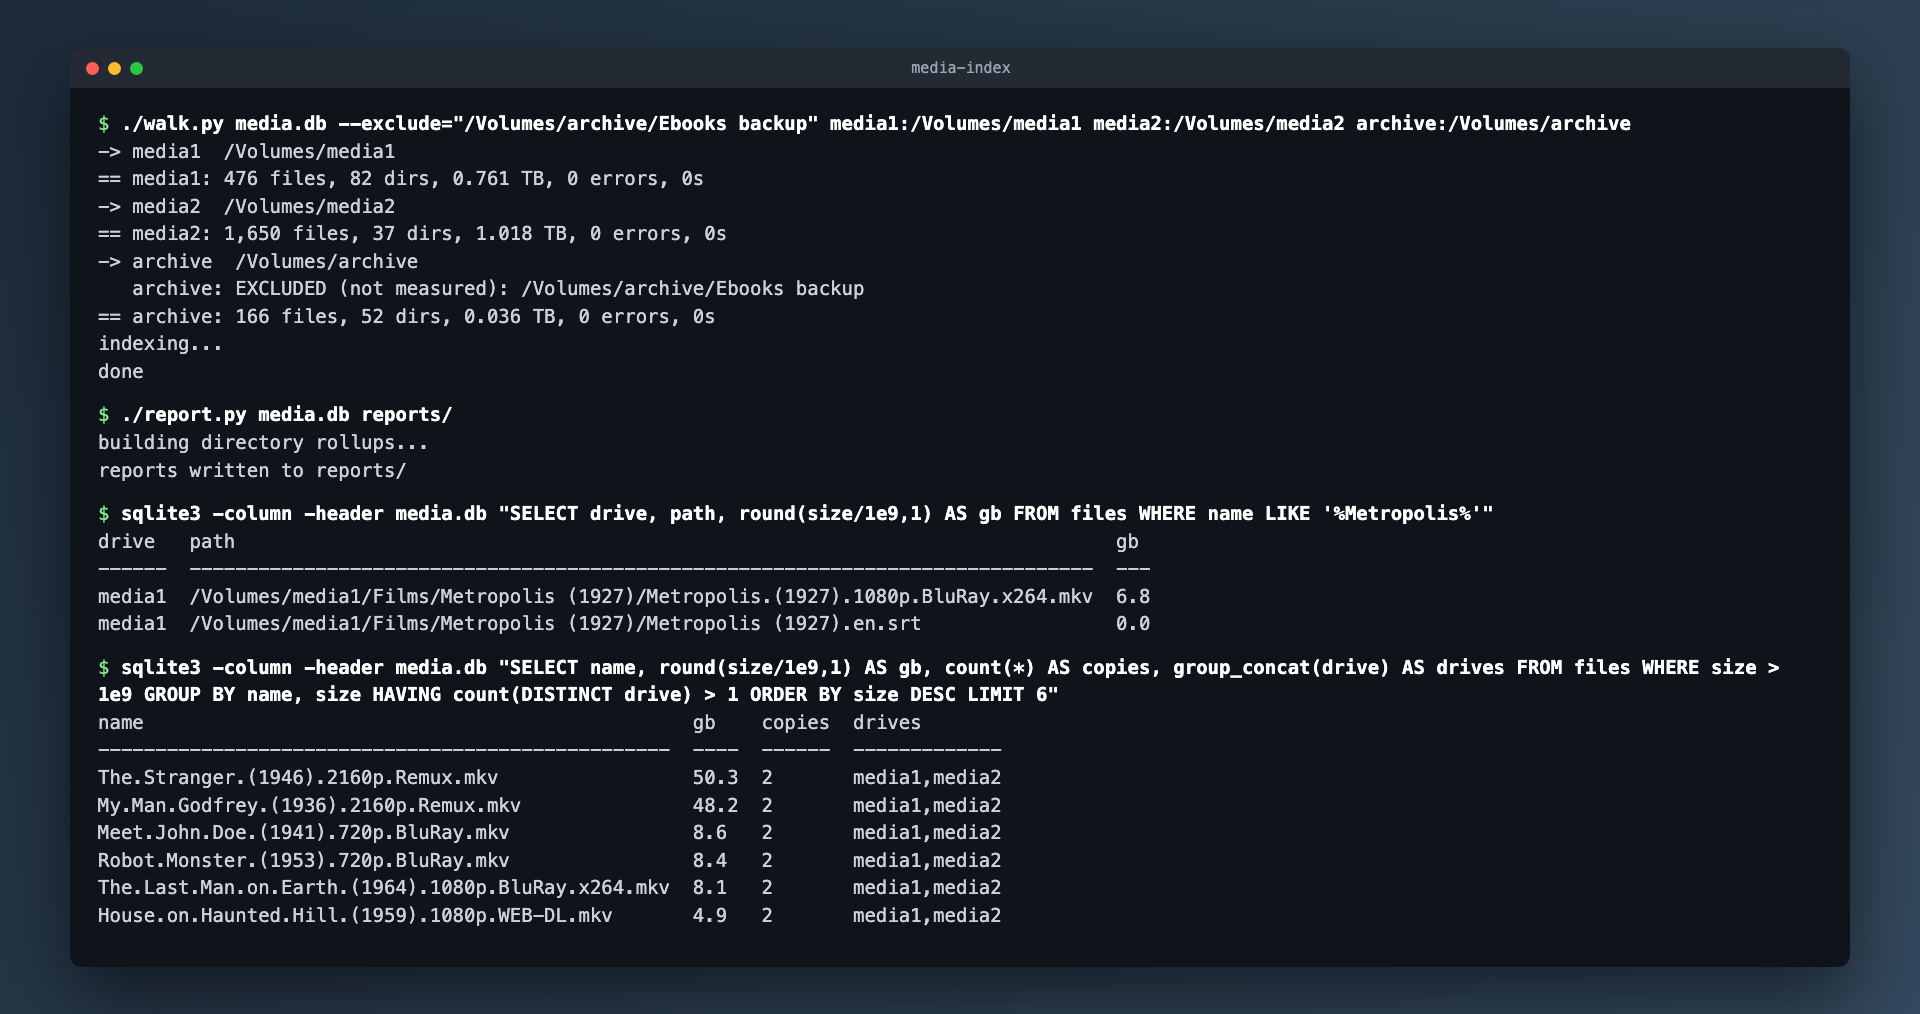
A metadata-only indexer for a large media estate. It walks every drive and records each file’s path, size, modification time and type in one SQLite database, so “do I own this?”, “which drive is it on?” and “what’s stored twice?” become queries instead of another afternoon of spinning up disks.
On my own drives it indexed 2.16 million files, about 30 TB, in roughly thirteen minutes.
It’s strictly read-only and fast on spinning disks: directory metadata only, never a hash or a file’s contents, with batched inserts and one process per physical drive so the spindles work in parallel. Noisy trees like node_modules are summarised in one row, and every report says plainly what it didn’t measure rather than claiming coverage it doesn’t have.
Reports roll it all up in Markdown: per-drive totals, films with likely duplicates and low-quality copies, TV series with missing episodes, and cross-drive duplicates by name and exact size.